📦 DVC applies Git best practices to data, models, and data-science experiments. Its goal is making Machine Learning projects reproducible and easy to share.
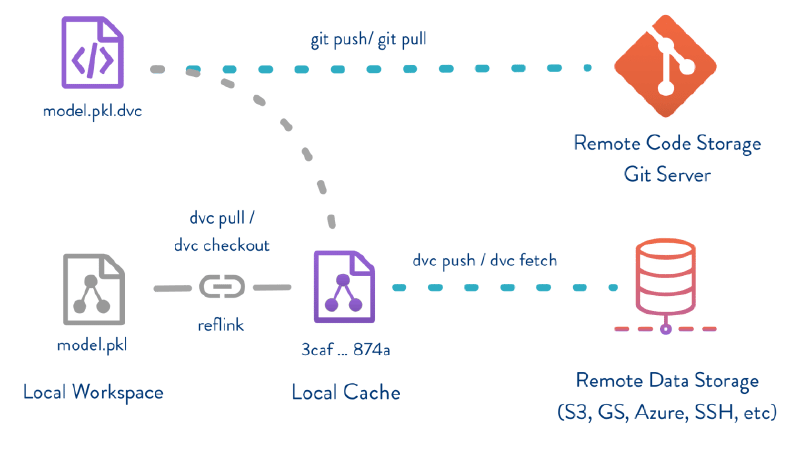
🔗 Large files do not need to live inside a Git repository. DVC keeps their versions and metadata in the project while storing data in a local cache or remotes such as S3, Azure, Google Cloud, or on-premises servers.
⚙️ It also describes pipelines connecting code, data, commands, and outputs. When something changes, only affected steps run. Experiments can be executed, compared, and shared through their metrics without requiring a central server.
The author presents an experience similar to combining Git for data, Makefiles for pipelines, and a local experiment-tracking system. DVC works from the command line and offers a VS Code extension.
💡 Explanation in a nutshell#
Git is excellent for code, but datasets and models are often too large. DVC stores a lightweight reference in Git and keeps heavy files outside the repository, allowing you to return to any version and reproduce how a result was obtained.
More information at the link 👇
